Keep your quality while AI writes more of your code.
AI writes more of your code every month and you are still the one who has to read all of it. Two ceilings, six practices and the lifecycle around the code, all of it from running an AI-operated delivery process on a live product past 165,000 lines as at 2 August 2026, including the parts that went badly, which are the useful parts.
No email required. Nothing gated. If you take all of it and never speak to us, the playbook has done its job.
The six practices on a page
Each has a first move you can make this week and a first number to watch. None needs our software. Press a practice to read it.
- 1A person can finish the jobChapter 4
- First move
- Write the sentence a customer would say when it works
- First number
- Journeys defined, and journeys completing
- 2Gates tighten as the codebase growsChapter 5
- First move
- List what your coverage number excludes
- First number
- Coverage of changed lines
- 3Idle is reported, not hiddenChapter 6
- First move
- Add “Waiting” and “Blocked” states and move items where they belong
- First number
- Active share of elapsed time, per stage
- First move
- Sort blocked items to the top, with their age
- First number
- Blocked now, and the median age
- First move
- Recompute the number you would be most embarrassed to find wrong
- First number
- Places a metric is typed (target: one)
- First move
- Make one guard fail on purpose and see whether it catches it
- First number
- Share of changes blocked by each rung
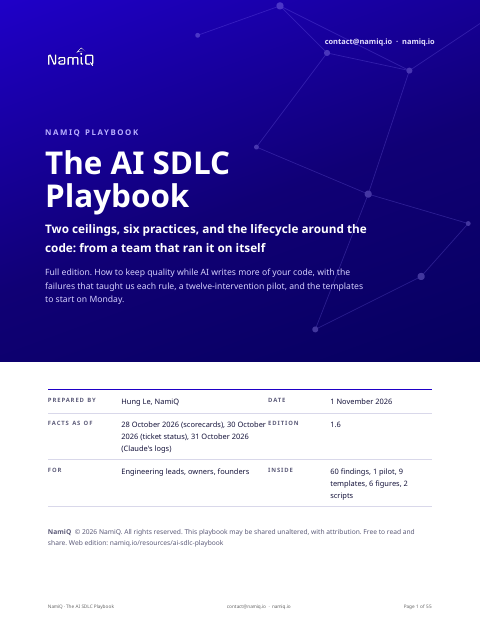
The full edition
The page below is the short version. The full edition is the one to keep: 18 chapters and 7 appendices, one for each practice with how to start, how to measure it and the anti-patterns, and the failure from our own record that taught us the rule. Then the lifecycle around the code, the pilot in which one real requirement needed 12 manual interventions, the 60 findings behind it, a self-assessment, a 30, 60 and 90 day plan, and 9 templates. 6 figures, and the whole playbook on page 2. Every chapter opens with what you will be able to do and ends with something you can do in ten minutes.
Three pages of it as they are, so you can judge the level. Press a page to open it full size.
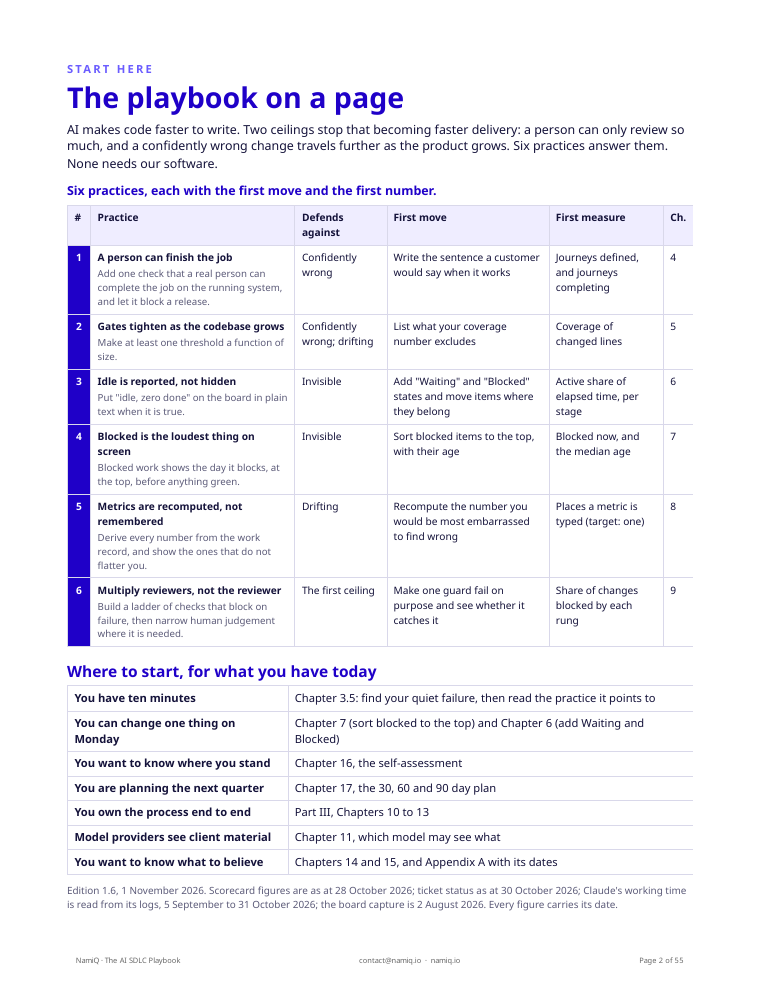
Page 2. The playbook on a page, and where to start for what you have today.
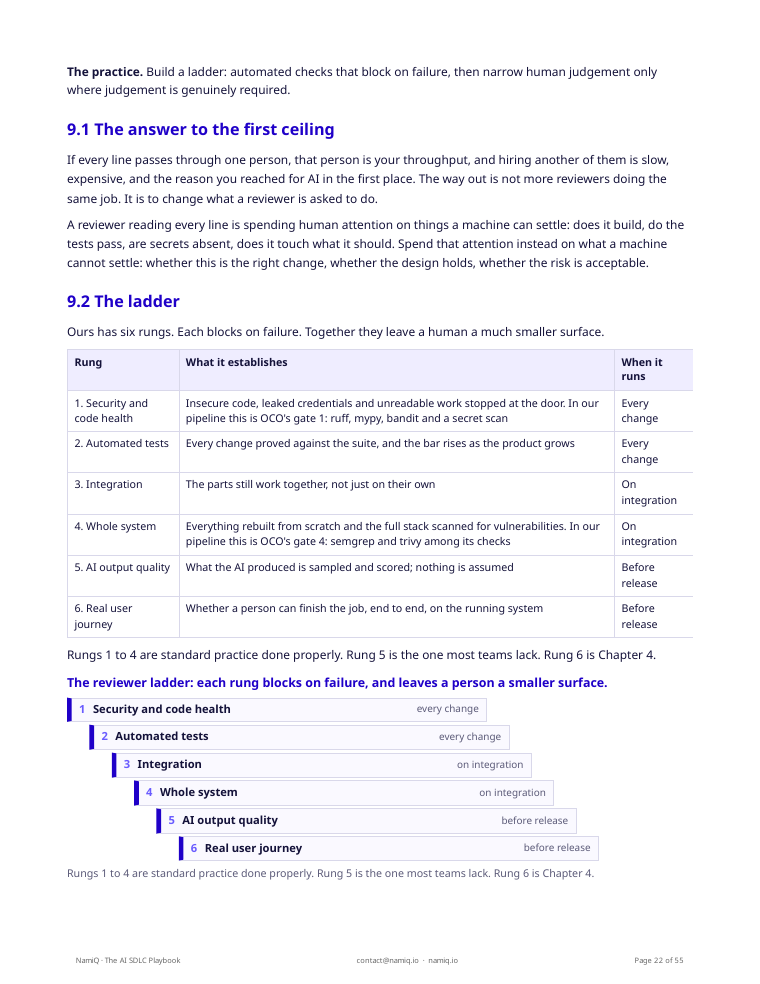
A chapter page. Each chapter opens with what you will be able to do, the one idea to keep, and a ten-minute exercise.
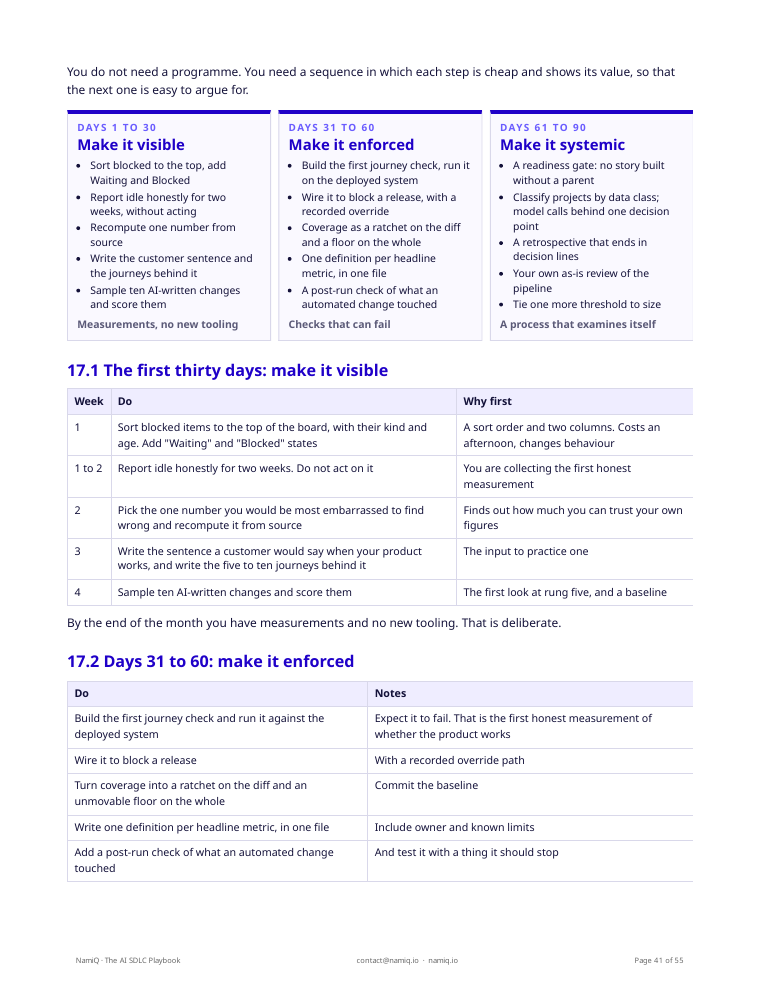
The plan. Thirty days of measurement and no new tooling, then enforcement, then a process that examines itself.
Who it is for
Engineering leads
You own how work reaches production and need the gates, the board and the metrics to hold as AI writes more of it. Part II, and the reviewer ladder.
Founders and owners
You cannot read every change and need to know the product works for a person. Practice one, the self-assessment, and the thirty-day plan.
The process owner
You hold the gates and hear every “this check is wrong”. Part III, the metric definitions, and the record of what broke in ours.
1The two ceilings
Coding was never the only process in building software, just the one that got faster first. Requirements, design, security review, testing and release are most of the real work, and none of them sped up because generation did. Point AI at “write the feature” without touching the rest of the lifecycle and you have handed a slower pipeline more raw material than it can absorb.
AI can 10× how much code gets written. It cannot 10× how much a human can safely review. If every line still passes through one person's eyes, that person's reading speed is your real ceiling — no matter how fast the model is.
AI is excellent on day one: a blank file and an afternoon get you a week of senior work. Real products cross into six figures of lines, where parts depend on each other in ways nobody wrote down. The model does not get worse — the blast radius of confidently wrong grows with the codebase, and nothing tells you unless something is built to.
Those were written in July 2026. The industry has since measured the same thing:
- 1.7× more issues in pull requests containing AI-assisted code than in human-written code — arXiv preprint 2603.28592, March 2026
- 30–41% rise in technical debt within six months of widespread AI tool adoption — Innovative Group, 2026
- 45% of AI-generated code introduced a security vulnerability — Innovative Group, 2026
- 4× maintenance costs by year two, for teams that do not actively manage the debt — Innovative Group, 2026
Published figures, directional rather than audited. Three of the four come from the same 2026 analysis; the first is a separate preprint. Every one is linked so you can weigh it yourself.
2Green tests can sit over a broken product
Our test suite passed. Coverage was at 80%, the figure on our published board as at 2 August 2026. Every gate reported success — and two screens were failing to load, with exactly one of nine customer journeys completable end to end.
That is not a criticism of testing; it is the definition of it. A test encodes an expectation, and an expectation is something a person had. The failures that hurt are the ones nobody expected, which is precisely the set no test covers. More tests push the boundary outward, and the boundary never closes.
The practice: add one check that asks whether a real person can finish the job on the running system, and let it block a release.
It is the one signal that cannot be satisfied by writing more code to satisfy it. If you do nothing else on this list, do this.
3Gates must tighten as the codebase grows
What was good enough at 5,000 lines is not good enough at 165,000. The number of ways a system can be broken grows faster than the system does, so a fixed quality bar is a falling one — and it fails quietly, which is the worst way to fail.
The practice: make at least one threshold a function of size.
Coverage requirements, review depth, how much of the system a change may touch without extra scrutiny. This is unpopular with anyone who wants a stable definition of done, and it is the only version that stays honest as the product grows.
4Idle is a status to report, not hide
Every delivery process has idle time. Processes that hide it do not have less of it; they have the same amount plus a reporting layer that obscures where it went.
The practice: put “idle, zero done” on the board in plain text when it is true.
It changes behaviour faster than any stand-up, because it is visible without anyone having to raise it — and raising it is exactly what people avoid doing.
We also got this one wrong, and it is the best example we have. Our scorecard printed a share of elapsed time spent working: 28% on 2 August, then 3% on 28 October. Both were withdrawn on 31 October 2026. The scorecard divided the average time a resolved ticket took by that time plus the average age of the tickets still open. They are different tickets. On 28 October the “idle” side was the average age of about two dozen open tickets, not time spent waiting inside the resolved ones, and it grows by itself as a backlog ages. It said nothing about how much time anyone or anything spent working. The ticket system records two times per ticket, created and resolved, so it cannot say how long a ticket was worked on or waiting. A correct per-ticket figure needs the state changes recorded.
What we can measure is the work itself, from Claude’s own logs. Between 5 September to 31 October 2026 Claude worked on 51 of 57 days, about 100 hours in all, and about a fifth (20% to 22%) of that ran on a branch that names a ticket. The rest was the website and other work no ticket records, so a ticket board saw a fifth of it. The figures and how they were read are on the board page. The practice stands, and so does its price: record the state changes, or you will measure something else and believe it.
5Blocked should be the loudest thing on screen
Blocked work is the most expensive state in any pipeline and usually the least visible. It surfaces at the next stand-up, or in a status report, or three weeks later when someone asks why a feature never shipped.
The practice: blocked work shows the day it blocks, at the top, before anything green.
6Recompute metrics, do not remember them
A number updated last Friday is a story, not a fact. Any metric maintained by hand drifts from reality at exactly the rate that makes it dangerous: slowly enough to keep trusting, fast enough to be wrong when it matters.
The practice: derive every number from the work record, and show the ones that do not flatter you.
Ours, on the position as at 2 August 2026, reports that 43% of work was later redone — a figure we publish with the caveat that there is no published industry norm to compare it against, so treat it as our own watch item and not as a benchmark you have beaten. The same board shows queueing time rising as more work ran in parallel; we can show the direction and not a magnitude we would defend, so take it as a direction. Publishing both is not humility, it is self-interest: a board that can only show good news tells you nothing on the day something goes wrong, which is the only day you urgently needed it.
7Multiply reviewers, not the reviewer
This is the answer to the first ceiling. If every line passes through one person, that person is your throughput — and hiring another of them is slow, expensive, and the reason you reached for AI in the first place.
The practice: build a ladder. Automated checks that block on failure, then narrow human judgement only where judgement is genuinely required.
Ours is six checks: code health and secrets, tests, integration, a full rebuild with a vulnerability scan, a sampled score of what the AI actually produced, and finally whether a person can finish the job. A human still decides — on a much smaller surface.
8The lifecycle around the code, and what broke
The six practices live inside a longer path. Most AI-assisted teams put AI at the code and leave the rest as it was, and the largest gain turned out to be in the stages before it: a chain from a requirement to a ticket that someone could build without asking, with every link naming its parent and a readiness gate that refuses a story whose chain is broken.
- S0IntakeA requirement, with an id
- S1Understand what existsEvidence, with its unknowns listed
- S2ExploreA brief
- S3RequirementsOwner acceptsA specification
- S4SolutioningLead acceptsDesign and decision records
- S5BacklogEpics and stories, each falsifiable
- S6Readiness gategateReady, or bounced. Fails closed
- S7Build in a fenceOwn copy, own branch, enforced boundary
- S8Review and testLead reviewsSix checks, then a person
- S9Close and adaptRetrospective ending in decisions
- S10KnowledgeWhat was learned, linked to its source
- 1A person can finish the job
- 2Gates tighten with size
- 3Idle reported
- 4Blocked loudest
- 5Metrics recomputed
- 6Reviewers multiplied
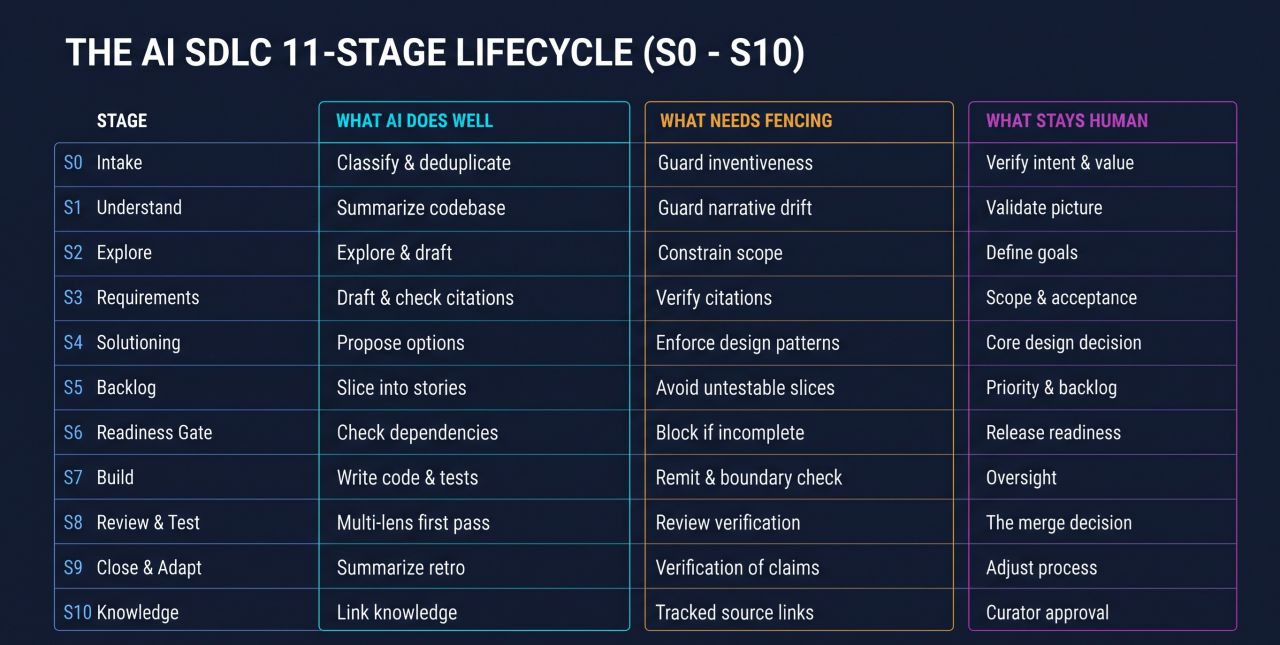
Read it as a table
| Stage | What AI does well | What needs fencing | What stays human |
|---|---|---|---|
| S0 Intake | Classify & deduplicate | Guard inventiveness | Verify intent & value |
| S1 Understand | Summarize codebase | Guard narrative drift | Validate picture |
| S2 Explore | Explore & draft | Constrain scope | Define goals |
| S3 Requirements | Draft & check citations | Verify citations | Scope & acceptance |
| S4 Solutioning | Propose options | Enforce design patterns | Core design decision |
| S5 Backlog | Slice into stories | Avoid untestable slices | Priority & backlog |
| S6 Readiness Gate | Check dependencies | Block if incomplete | Release readiness |
| S7 Build | Write code & tests | Remit & boundary check | Oversight |
| S8 Review & Test | Multi-lens first pass | Review verification | The merge decision |
| S9 Close & Adapt | Summarize retro | Verification of claims | Adjust process |
| S10 Knowledge | Link knowledge | Tracked source links | Curator approval |
We redesigned our own lifecycle this way in October 2026, then ran it on itself. The record is in the full edition, including the parts that went badly. One real requirement went through the whole chain on 22 October 2026 and needed 12 manual interventions: 6 were factory defects, fixed during the run; 4 more were still open when we wrote it up and were fixed the next day (ODSF-264, ODSF-265, ODSF-266, ODSF-267, closed 23 October 2026); 2 were human gates working as designed. We have not re-run the pilot, so we cannot yet say the same path now needs fewer. The log of findings from the build stands at 60 as at 28 October 2026. The most common shape among them is something reporting success for a reason that was not success: a boundary check that found nothing to enforce, a ticket marked done for work that never landed, a build that hit its turn limit and reported ok.
We would rather you saw the number 12 than a demo with none. It is also the most transferable thing here: build a lifecycle from parts and the first month goes on the joins between them. The pilot, step by step →
9Secure development: check what the build depends on
AI-assisted work adds dependencies faster than anyone reads their advisories: a model writes a package name and a version from memory. The cheapest place to notice an exploited dependency is where it is declared, so we added one check to the build. It reads a project’s manifests (requirements, package.json, Maven, Gradle, Cargo, CMake, Dockerfiles and compose files), asks Latticeabout CISA’s exploited vulnerabilities, and compares each declared package with the product CISA names. It runs the same way on a laptop and in CI, with make dep-scan in every product the factory builds.
Our first run, on 2 November 2026: 7 projects, 99 manifest files, 2,964 declared components, 2,523 of them pinned to a version, against 9 named exploited CVEs. 13 declared packages matched an exploited product. None was inside an affected range, 5 were outside every range and 8could not be judged. Five of those eight were the scanner’s own mistake (a client library with the server’s name), which is why it now has a separate verdict, lead. 3 remain, each with a written reason.
Read the answer as evidence, never as a verdict: it says what a manifest declares, not what is deployed, and it does not say a project is safe. Without a key you can name the CVEs you care about; with a key whose email is confirmed it reads the whole CISA list. It is a command a person runs in our factory today, not yet a gate that blocks a merge. The method, the numbers and the mistakes are in Appendix G of the full edition, and the guide to the command line, the skill and the MCP has a CI recipe. The deployment step has a check too: the same tool, without its project subcommand, reads the packages, snaps, running images (their operating system and packages) and kernel of the server a release lands on (Appendix G.6). The graph it reads is Lattice, and the package is on PyPI and in the signed apt repository.
10What to adopt on Monday
Cheapest first. The first two cost an afternoon between them, and the last takes ten minutes.
- Put blocked at the top of your board. A sort order change. Costs nothing.
- Report idle honestly for two weeks. Do not act on it yet. Just look at it.
- Pick one number and recompute it from source. Whichever one you would be most embarrassed to find is wrong.
- Add one end-to-end journey check for the single path that matters most, and let it block a release.
- Sample AI-written changes and score them. Ten a week is enough to see a trend.
- Tie one threshold to codebase size so the bar moves without anyone having to argue for it.
- Scan one project’s declared dependencies against two CVEs that matter to you, and read every row.
None of this requires our tooling, and we would rather you did it yourself than hired anyone. The one thing worth reading next is what happens when a team actually runs all six: our own board, as at 2 August 2026, with the rework and queueing rows left in. It is the only page here that is mostly numbers, including the ones we would rather not print.
Questions
- Is it free?
- Yes, and there is no email step. The web page and the full edition are open.
- Do I need your software?
- No. Nothing in the six practices needs it, and we would rather you did them yourself than hired anyone.
- Is it a benchmark?
- No. The product the numbers come from is our own, where we set the scope and chose the stack, which is the friendliest case there is. Discount it accordingly.
- How current is it?
- Edition 1.7, 2 November 2026. Scorecard figures are as at 28 October 2026, ticket status as at 30 October, and the board capture is 2 August. Every figure carries its date, and the ones we have not reconciled say so.
- Can I share it?
- Unaltered, with attribution. The cover says so.