Everything below comes from one build. Ours.
One operator and twelve specialist roles, on a live cybersecurity product. Position as at 2 August 2026, recomputed from the work record — not a snapshot anyone typed in.
These are a dated capture, not a live feed. The board they come from keeps running, and the figures move with it — up and down.
This is a case study, not a track record. Every figure on this page comes from a single product that we built for ourselves, which means we also wrote the requirements and set the deadlines. That is an easier problem than a client engagement, and you should discount accordingly. The full case study says what it does and does not prove.
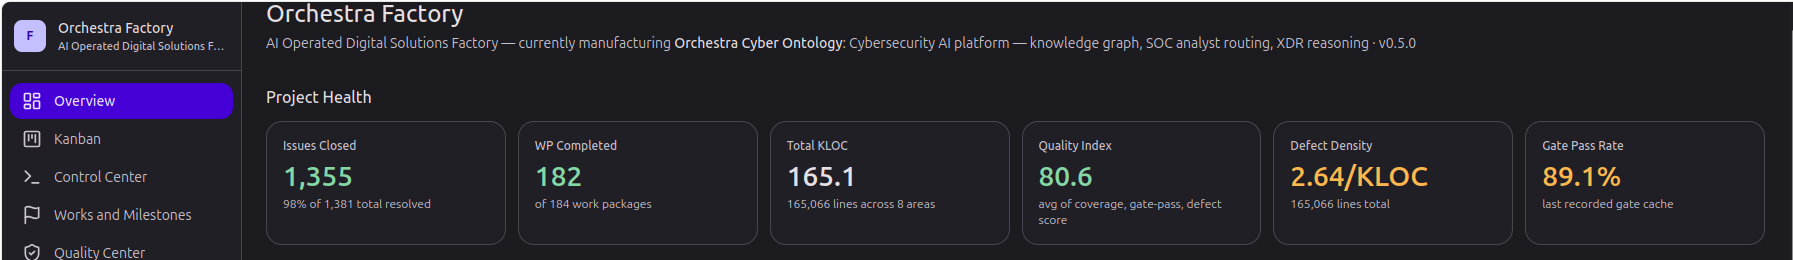
The position on 28 October 2026, after the AI SDLC renovation.
The capture above is from 2 August 2026. This is the same two boards three months on, read straight from their scorecards that day: the product, and the factory itself. Both stay in, because a board that can only show good news tells you nothing on the day something goes wrong.
- Defects per 1,000 lines: 3.41, up from 2.64. We read this as the checks catching more issues, and catching them early in development, where they are cheapest to fix. A smaller line count after a refactor also raises it.
- Work later redone: 43% as at 2 August 2026, a watch item with no published norm to compare against. The scorecard does not carry it, so there is no newer figure.
- Queueing: time lost rose as more work ran in parallel. That is a direction, not a magnitude we would defend.
| Scope | Measure | Value | Read |
|---|---|---|---|
| The product | Issues closed | 1,391 of 1,415 (98%) | |
| The product | Work packages completed | 178 of 179 | |
| The product | Lines of code | 136,631 | Down from 165,000 after a refactor |
| The product | Quality index | 77.3 | Down from 80.6 |
| The product | Defects per 1,000 lines | 3.41 | Up from 2.64. We read it as the checks catching more issues, early in development |
| The product | Gate pass rate | 89.1% | |
| The product | Time actually spent working | Withdrawn (was 3% of elapsed) | Computed from two different groups of tickets. See the note below the table |
| The factory itself | Issues closed | 233 of 254 (92%) | |
| The factory itself | Lines of code | 92,435 | |
| The factory itself | Quality index | 83.2 | |
| The factory itself | Defects per 1,000 lines | 1.17 | A smaller and newer codebase |
| The factory itself | Time actually spent working | Withdrawn (was 2% of elapsed) | Computed from two different groups of tickets. See the note below the table |
| Claude's working time | Days Claude worked | 51 of 57 days | 5 September to 31 October 2026. The logs go back no further, so nothing earlier can be measured this way |
| Claude's working time | Working time | about 100 hours; median 1.4 hours on a working day | 82 to 103 hours, depending on how long a pause still counts as working. Parallel sessions are counted once |
| Claude's working time | Working time on a branch that names a ticket | about a fifth (20% to 22%) | The rest ran on the website, the factory home and other work no ticket names, so a ticket board sees about a fifth of it |
| Claude's working time | Share of a ticket's working span spent working | 21% (median ticket; 11% to 21% over the thresholds) | 74 tickets with Claude time on their own branch, first to last Claude activity. Middle half of tickets 2% to 100%; 0.12% of the time from creation to resolution |
| Claude's working time | Share of a working session spent working | 68% (52% to 80%) | The rest is a person reading and typing. The range is how long a pause counts |
| The renovation | Epics closed | All ten (E0 to E9) and the pilot epic | |
| The renovation | Dogfood findings logged | 60 | 30 fixed, 14 design changes, 18 ticketed |
| The renovation pilot | Manual interventions for one requirement | 12 | 6 fixed in the run, 4 fixed the next day (ODSF-264 to 267), 2 human gates by design. Not re-run since |
We published 28% on 2 August 2026, and 3% (the product) and 2% (the factory) on 28 October 2026. The scorecard divided the average time a resolved ticket took by that time plus the average age of the tickets still open. They are different tickets. On 28 October the “idle” side was the average age of about two dozen open tickets, not time spent waiting inside the resolved ones, and it grows by itself as a backlog ages. It said nothing about how much time anyone or anything spent working.
The ticket system records two times per ticket, created and resolved, so it cannot say how long a ticket was worked on or waiting. A correct per-ticket figure needs the state changes recorded. The rows headed Claude’s working time are read from Claude’s own logs on 31 October 2026.
The same rows are in Appendix A.2 of the AI SDLC Playbook. The pilot row is the pilot report.
How to read this record
- Every number has a date and a scope. The capture is 2 August 2026; the position is 28 October 2026. Never compare a figure from one with a figure from the other without saying so.
- Where they disagree, both are printed. A dashboard that only goes up is a marketing asset. We wanted an instrument, and an instrument has to be able to read low.
- There is no second version. The board a client sees is the one we run on. The moment a metric exists to be presented rather than read, the real numbers migrate into private spreadsheets.
- Ask any supplier for the number that got worse. If every figure they give you flatters them, discount all of them, because you cannot tell which ones deserved it.
- None of this makes the work cheaper by itself. It makes the work legible, and legible work is the only kind you can improve.
We can tell you what a change costs before you commit to it.
Cost is metered per item, per feature and per specialist, on the same board that reports progress. That is unusual enough to be worth saying plainly — and it changes what a scope conversation can be about.
Metered per item, not estimated
Rework is its own line
Scope becomes a value question
Against what comparable work normally takes
| Measure | This factory | Typical for comparable work | Read |
|---|---|---|---|
| Work delivered as committed | 94–96% | 60–85% | Better |
| Test coverage | 80% | 70–80% target | In line |
| Defects per 1,000 lines | 2.64 | 1–5 for a disciplined team | In line |
| Effort to reach this scope | ≈ 1 person-month | ~200 person-months | Far lower |
| Calendar time to reach it | 17 days | 9–18 months | Far lower |
| Work later redone | 43% | no published norm | Watch item |
"Typical" means commonly published software-engineering ranges for work of comparable scope. The effort and calendar rows are an order-of-magnitude estimate, not a precise measurement — shown with that caveat rather than without it.
A row for time actually spent working (28%, read as better than the typical 10 to 20%) was in this table until 31 October 2026. It is withdrawn: the figure did not measure that. Why.
It is not built around one project.
The factory and its first product grew up together. The third product — an unrelated business, on an unrelated technology — is the evidence it transfers.
A cybersecurity platform
The factory itself
An education platform
See what it reports about your system.
Pointed at a system nobody fully understands any more, the factory maps it and reports where the gaps are in about ten minutes — without overwriting a single existing document. Your prior work is input, not something we replace.
Talk to us